
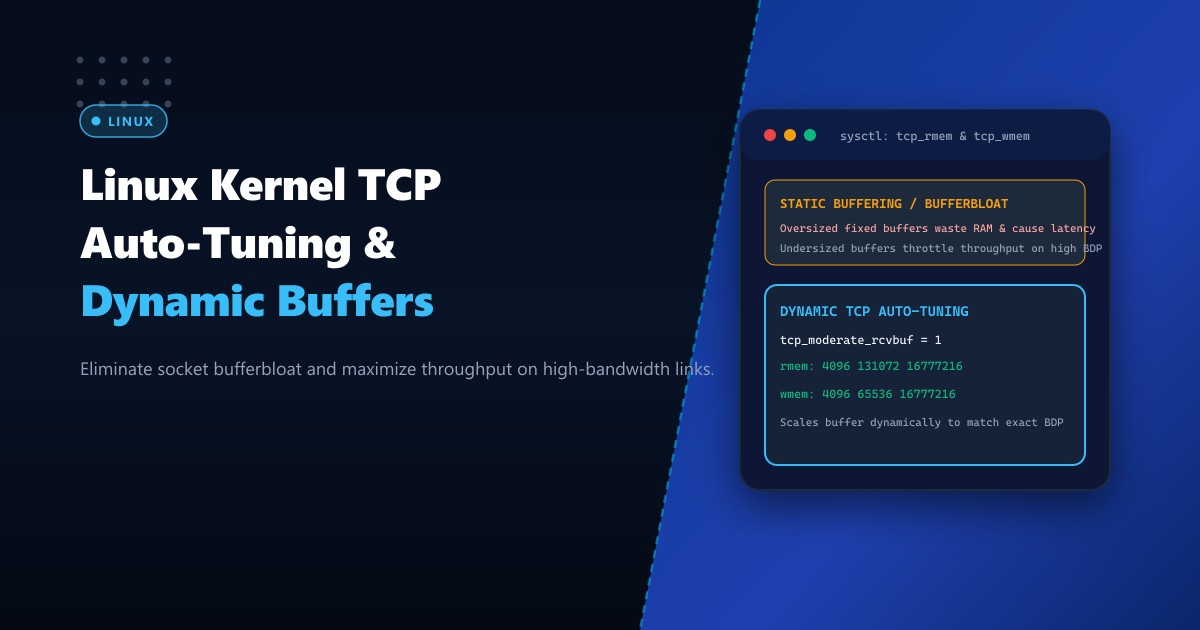
In high-bandwidth Linux hosting environments across Pakistan—powering video streaming CDN edges, file storage clouds, database replication clusters, and enterprise API gateways—maximizing network throughput while keeping round-trip latencies ultra-low is a core systems engineering challenge.
Network throughput is fundamentally governed by the Bandwidth-Delay Product (BDP): $$\text{BDP} = \text{Link Bandwidth} \times \text{Round-Trip Time (RTT)}$$
For example, a 10Gbps dedicated connection serving clients across high-RTT trans-oceanic routes (e.g., Pakistan to Europe at 150ms RTT) requires a socket buffer of at least: $$10\text{ Gbps} \times 0.15\text{ s} = 1.5\text{ Gigabits} \approx 187.5\text{ Megabytes!}$$
If socket memory buffers (tcp_rmem and tcp_wmem) are constrained to legacy static limits (such as 128KB or 2MB), the sender must pause transmission after every burst to wait for ACKs, artificially choking a 10Gbps link down to a mere 100Mbps!
Conversely, blindly setting static 64MB buffers across thousands of simultaneous connections causes severe bufferbloat, exhausts kernel SLUB slab caches, and inflates packet queuing delays from 15ms to over 800ms.
The solution is the Linux kernel’s Dynamic TCP Window Auto-Tuning (tcp_moderate_rcvbuf) backed by three-tier vector configurations (min, default, max). By deploying on enterprise Dedicated Servers and tuning net.ipv4.tcp_rmem and net.ipv4.tcp_wmem, administrators unleash maximum line-rate throughput while preventing bufferbloat.
How Static Buffers vs. Dynamic Auto-Tuning Impact High-BDP Throughput
Here is the difference between static socket allocation and Linux kernel dynamic auto-tuning across variable RTT routes:
+-----------------------------------------------------------------------------------+
|               STATIC TCP BUFFERS vs. DYNAMIC AUTO-TUNING (BDP SCALING)            |
+-----------------------------------------------------------------------------------+
| Scenario: 10Gbps Dedicated Uplink | Pakistan to Singapore (80ms RTT)               |
| Required BDP Buffer: 10Gbps * 0.08s = 800Mb (100MB socket window)                 |
|                                                                                   |
| 1. Legacy Static Sizing (Undersized = Throughput Choke):                          |
|    - Buffer set to static 2MB.                                                    |
|    - TCP window fills after sending 2MB; transmitter stalls waiting for ACK!      |
|    - Maximum Achievable Throughput = 2MB / 0.08s = 200Mbps (Only 2% of 10G link!) |
|    - Result: Customers perceive slow file downloads despite paying for 10Gbps!    |
|                                                                                   |
| 2. Oversized Fixed Allocation (Memory Exhaustion & Bufferbloat):                  |
|    - 2,000 active connections allocated 32MB fixed RAM each = 64GB kernel RAM!    |
|    - Packets queue up in deep intermediate buffers; latency jumps to 800ms!       |
|                                                                                   |
| 3. Optimized 3-Tier Dynamic Auto-Tuning (`tcp_moderate_rcvbuf = 1`):              |
|    - `tcp_rmem = 4096 131072 33554432` (min: 4KB, default: 128KB, max: 32MB)     |
|    - Domestic client (10ms RTT): Allocates tiny 128KB buffer (saves system RAM).  |
|    - International client (150ms RTT): Dynamically expands window up to 32MB!     |
|    - Result: Perfect BDP line-rate throughput with zero queue latency or bloat!   |
+-----------------------------------------------------------------------------------+
Step 1: Auditing Current Kernel Socket Buffer Vectors
Linux manages socket receive and transmit buffers using 3-element integer vectors: [min, default, max].
Check your server’s current values:
sysctl net.ipv4.tcp_rmem
sysctl net.ipv4.tcp_wmem
sysctl net.core.rmem_max
sysctl net.core.wmem_max
sysctl net.ipv4.tcp_moderate_rcvbuf
Standard default values in older kernels:
net.ipv4.tcp_rmem = 4096 87380 6291456
net.ipv4.tcp_wmem = 4096 16384 4194304
net.core.rmem_max = 212992
net.core.wmem_max = 212992
net.ipv4.tcp_moderate_rcvbuf = 1
Notice net.core.rmem_max: If the global socket ceiling is 212KB, TCP cannot dynamically expand individual socket windows beyond that threshold even if tcp_rmem specifies higher values!
Step 2: Configuring High-Performance Dynamic Auto-Tuning
For servers operating on high-speed gigabit or 10-gigabit physical network uplinks, configure /etc/sysctl.d/99-tcp-autotuning.conf:
# 1. Expand global socket core memory ceilings (32MB ceiling per socket)
net.core.rmem_max = 33554432
net.core.wmem_max = 33554432
net.core.rmem_default = 262144
net.core.wmem_default = 262144

# 2. Dynamic TCP Receive Buffer Auto-Tuning Vector [min default max] (in bytes)
# Min: 4KB (prevents RAM waste on idle sockets)
# Default: 128KB (optimal baseline for domestic intra-Pakistan 10ms links)
# Max: 32MB (allows high-BDP saturation for international trans-oceanic transfers)
net.ipv4.tcp_rmem = 4096 131072 33554432

# 3. Dynamic TCP Transmit Buffer Auto-Tuning Vector [min default max]
net.ipv4.tcp_wmem = 4096 65536 33554432

# 4. Enable Dynamic Window Tuning in the receiver
net.ipv4.tcp_moderate_rcvbuf = 1

# 5. Enable TCP Window Scaling (RFC 7323) to allow windows > 64KB
net.ipv4.tcp_window_scaling = 1

# 6. Global TCP Memory Pool Limits (in 4KB memory pages) [min pressure max]
# For a 64GB RAM Dedicated Server:
# 64GB = 16,777,216 pages. Dedicate ~10% to ~25% to network stack:
net.ipv4.tcp_mem = 786432 1048576 1572864

# 7. Enable fair queueing packet scheduler to prevent bufferbloat
net.core.default_qdisc = fq
net.ipv4.tcp_congestion_control = bbr
Apply the updated configuration immediately:
sysctl --systemVerify that the kernel has loaded the expanded parameters:
sysctl -a | grep -E "tcp_rmem|tcp_wmem|tcp_moderate_rcvbuf|default_qdisc"Step 3: Inspecting Dynamic Socket Memory Allocation in Real-Time
To verify that the kernel is dynamically resizing socket buffers based on client RTT, inspect active connections using ss:
# View socket memory allocation on live HTTPS connections
ss -tm '( sport = :https )'
Sample output:
ESTAB 0 0 103.205.180.25:443 39.44.112.50:52184
     skmem:(r0,rb131072,t0,tb65536,f2048,w0,o0,bl0,d0)
ESTAB 0 0 103.205.180.25:443 142.250.27.27:443
     skmem:(r0,rb12582912,t0,tb8388608,f4096,w0,o0,bl0,d0)
Key Diagnostic Metrics Explained:
- Domestic Mobile Connection (
39.44.112.50):rb131072(128KB buffer). The kernel allocates only what is required, keeping memory footprint minuscule. - High-RTT International Transfer (
142.250.27.27):rb12582912(12MB buffer). The kernel automatically expanded the receive buffer to 12MB to saturate the high-BDP trans-oceanic link at full line speed!
Step 4: Tracking Network Memory Pressure & Bufferbloat
Verify that the server does not experience memory pressure drops:
# Monitor global TCP socket memory usage
cat /proc/net/sockstat
Output:
sockets: used 1240
TCP: inuse 890 orphan 0 tw 140 alloc 920 mem 8420
mem 8420: Memory consumed in 4KB pages (~33MB total across 890 active connections).- Because
tcp_moderate_rcvbufscales buffers down when links are idle, hundreds of concurrent connections consume negligible server memory while maintaining instant capacity to burst to 10Gbps!
Bare-Metal Dedicated Infrastructure for High-Throughput Pakistani Networks
High-velocity socket auto-tuning, kernel memory page management, and multi-gigabit TCP offloading demand unconstrained bare-metal hardware. Virtualized cloud droplets suffer CPU hypervisor interrupts and virtual switch packet serialization that cap TCP window scaling.
Hosting on enterprise Dedicated Servers in Pakistan equips your workloads with enterprise physical processors, 10Gbps/25Gbps hardware NICs with TCP Segmentation Offload (TSO) and Large Receive Offload (LRO), and direct domestic peering at PKIX.
Maximize Network Throughput with NextGen Dedicated Servers
Deliver multi-gigabit download speeds, eliminate socket bufferbloat, and guarantee flawless streaming and API performance across Pakistan. NextGen dedicated hosting provides pure bare-metal power, enterprise hardware firewalls, and 24/7 technical management.
Deploy Dedicated Servers in Pakistan